Why blank spaces matter
A dataset can look complete enough to answer a question while leaving out the people, events, or measurements that matter most. Imagine a customer survey in which many respondents rate their experience, but few answer a question about why they stopped using a service. The ratings describe those who supplied them; they do not necessarily explain why others left. Before treating a result as representative, ask who or what had the chance to appear in the data.
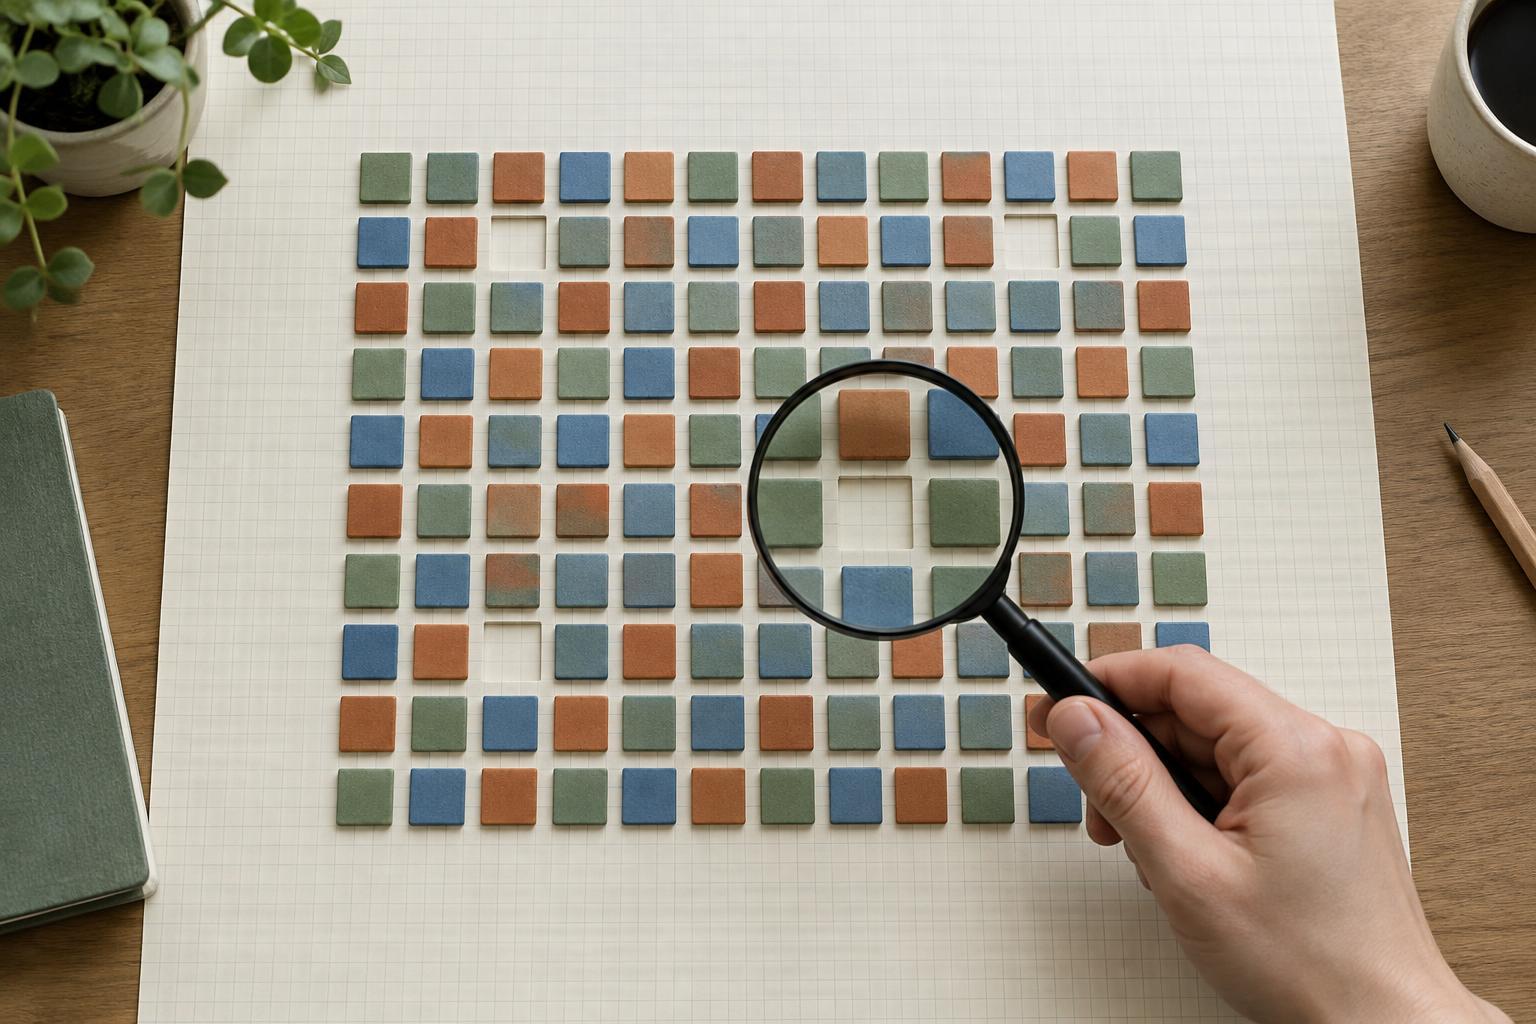
Missing data includes more than empty cells. A form may skip a question, a sensor may stop recording, or an organization may never collect information from a particular group. These gaps can affect a single calculation or the entire picture. Their importance depends less on the number of blanks alone than on whether the missing cases differ from the cases you can see.
Start by locating the gaps
First, identify the unit being counted: people, purchases, visits, days, or something else. Then compare the number of records available for each measure. If a report gives an average satisfaction score, find out how many people provided a score and how many were invited to do so. An average based on some responses should not quietly become a claim about everyone.
Look for patterns in where values are absent. Are blanks concentrated in a particular time period, location, product type, or question? Does a missing answer tend to accompany another missing answer? A table showing the count of available and missing values for each field can make these patterns easier to see. If the dataset has several steps, such as visits followed by sign-ups and purchases, check where records drop out between steps.
Also distinguish a missing value from a meaningful value such as zero. Zero purchases may mean a customer bought nothing; a blank purchase count may mean the transaction history is unavailable. Combining the two changes the question being answered.
Ask why information is missing
Some gaps arise for routine reasons. A question might apply only to people who selected a certain option earlier, or a device might fail briefly without regard to what it would have measured. Other gaps may be related to the value itself. People with a very poor experience, for example, might be less willing to complete a follow-up survey. In that case, the available responses could give an overly favorable impression.
The reason is often uncertain. Rather than assigning one explanation to every blank, list plausible causes and consider what each would imply. Check the instructions used to collect the data, the timing of collection, and any changes in process. If you cannot tell whether nonresponse is related to the outcome, say so. A precise calculation cannot remove uncertainty about who is absent.
Test how much the conclusion depends on the missing values
There is no single fix for every gap. Excluding incomplete records may be reasonable for a narrow question, but it can discard useful information or change the makeup of the group being studied. Filling blanks with a typical value keeps a table tidy, yet it can hide variation and make an estimate look more certain than it is. Neither choice should happen silently.
For a practical check, compare the result under a few clearly stated assumptions. What happens if you use only complete records? Does the result change when you examine groups with different rates of missing answers separately? If the missing cases could plausibly have lower or higher values than the observed cases, would either possibility reverse the main conclusion? These checks may not reveal the true answer, but they show whether the finding is sturdy or depends on an untested guess.
When the gap is large or concentrated among an important group, the most useful next step may be better collection rather than a more elaborate calculation. A shorter question, clearer response options, or a way to record why a value is unavailable may help with future decisions.
Describe the limits alongside the finding
A clear summary tells readers what was measured, how many observations were available, and what was missing. Instead of saying, “Customers prefer option A,” a more careful statement might say that option A was preferred among customers who answered the question, while noting that preferences among nonrespondents are unknown. The qualification is part of the finding, not a footnote to dismiss.
Missing data does not automatically make a dataset useless. It does set a boundary around what the dataset can support. By locating gaps, considering their causes, and checking whether reasonable assumptions change the result, you can draw conclusions that are both useful and appropriately cautious.