What makes a value an outlier?
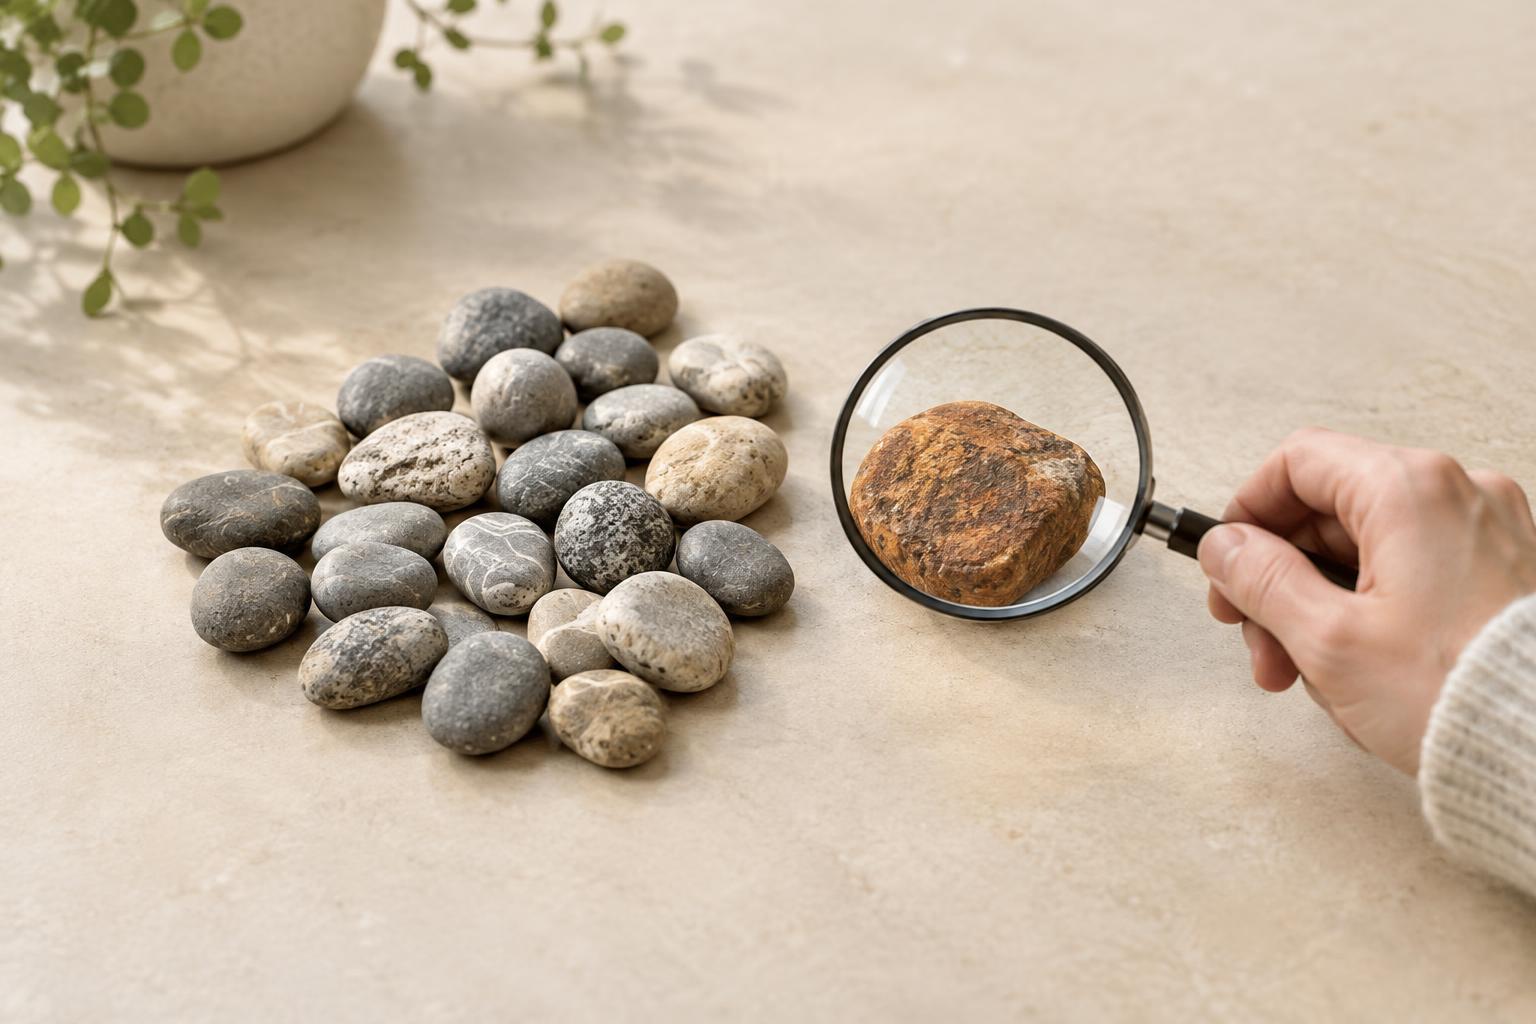
An outlier is a value that stands apart from the rest of a dataset. Imagine a list of delivery times in which most orders arrive within a similar window, but one takes much longer. That delivery is worth noticing. It is not, by itself, proof that the data is wrong or that the delivery process has changed.
Whether a value counts as unusual depends on the question and the comparison group. A long delivery time may look exceptional among orders within one neighborhood but ordinary among orders shipped across a wider area. Before labeling a value an outlier, check that the observations measure the same thing, use the same units, and belong in the same comparison.
Why unusual values matter
An outlier can change a summary, especially the average. A small number of very high values can pull the mean upward even when most observations remain low. The median, which identifies the middle value in an ordered list, is usually less affected by extremes. Looking at both can reveal whether an average describes a typical observation or masks a wide spread.
Unusual values can also point to something the original question missed. An exceptionally long delivery might reflect an incorrect timestamp, a different shipping method, or a real service failure. Each explanation suggests a different response. Treating every outlier as an error risks removing important evidence; treating every outlier as a major discovery risks overstating a single case.
Start with the record, not the conclusion
When a value catches your eye, first inspect how it entered the dataset. Look for misplaced decimal points, inconsistent units, duplicate records, missing information, or entries that fall outside the period being studied. Compare the value with any relevant original record if one is available. A correction should follow evidence about what went wrong, not a preference for tidier results.
If the value appears valid, consider its context. Was it recorded under the same conditions as the other observations? Does it belong to a distinct group that would be more informative to examine separately? For example, comparing delivery times across different services may create apparent outliers simply because the services operate differently. Separating those groups may clarify the pattern without discarding any data.
Look at the pattern from more than one angle
A sorted list or a simple plot can show whether one value is isolated or whether several observations form a longer tail. Summaries such as the median, mean, range, and quartiles can add perspective, but no single measure decides what a value means. A cutoff for flagging outliers may be useful when applied consistently, yet it is a prompt for investigation rather than a verdict.
It also helps to check how much the unusual value affects the answer. Calculate a summary with all valid observations, then see how it changes if the flagged value is set aside for comparison. This is a sensitivity check, not permission to quietly delete inconvenient data. If the conclusion changes substantially, readers need to know that it depends on how the outlier is handled.
Explain the decision you make
There is no universal rule that says an outlier must stay or go. An entry confirmed as a recording error may need correction or exclusion. A valid but unusual observation may belong in the main analysis, perhaps alongside a second summary that shows its influence. If the value comes from a group outside the intended scope, explain that scope before excluding it.
A clear account answers three questions: What made the value stand out? What checks were possible? How did its treatment affect the conclusion? You do not need to turn every unusual number into a lengthy case study. A brief explanation can help others understand the limits of a summary and make a more thoughtful decision about what the data shows.