The question behind every experiment
Suppose a team changes the wording on a sign and then notices that more people follow its instructions. Did the new wording help? Perhaps. But the change could also reflect a busier day, a different audience, or another change made at the same time. Looking only at what happened after the sign changed leaves those possibilities open.
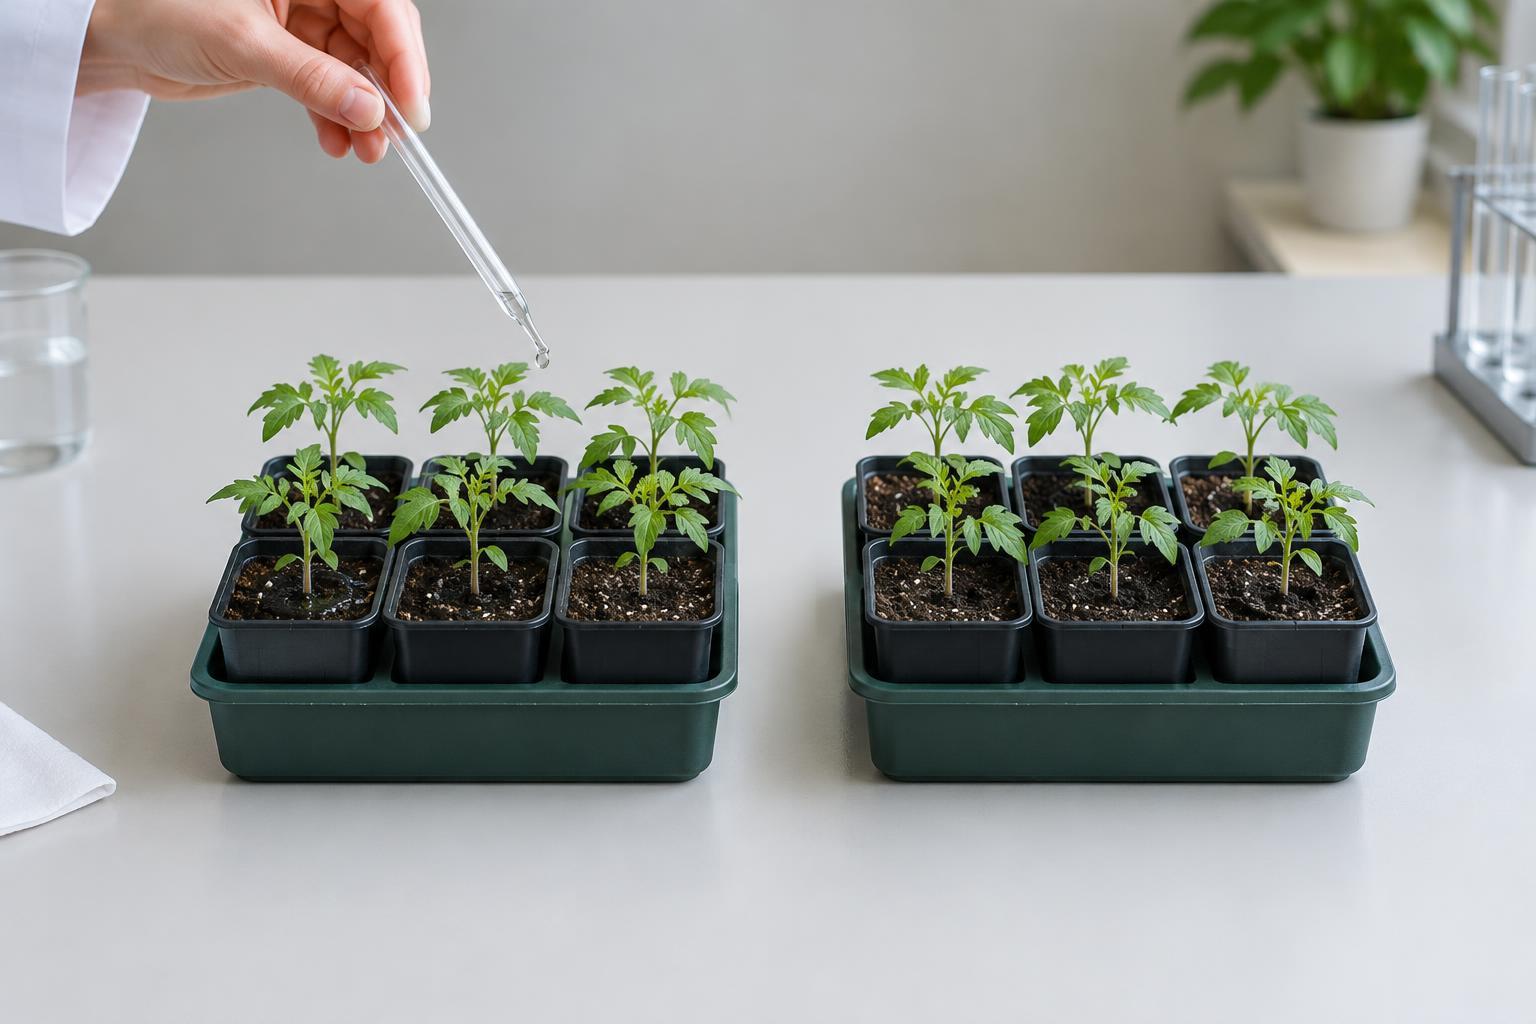
An experiment addresses this problem by comparing outcomes under different conditions. One group encounters the new wording; another encounters an alternative, such as the original sign. The second group provides a reference point for asking what might have happened without the new wording. That reference point is the purpose of a control group or comparison condition: it turns an observation into a more informative test.
What a control group controls for
A control group does not make an experiment perfect, and it does not mean that nothing happens to the people in it. Its job is to help account for influences shared by the groups. If both groups encounter the signs during the same period and in similar settings, a busy day may affect both. A difference between their outcomes is then less easily explained by that shared circumstance alone.
The central idea is to change one feature while keeping other relevant features as similar as practical. In a test of a new website layout, for example, both versions might offer the same products at the same prices. If one version also offers a discount, the test cannot cleanly separate the layout’s effect from the discount’s effect. Researchers call such competing explanations confounding factors. A comparison group is most useful when the conditions differ mainly in the feature the experiment aims to study.
The right comparison depends on the question
A control condition is not always an absence of action. It could be an existing product, a standard process, a neutral message, or a version designed to look similar without including the feature of interest. If the question is whether a new message works better than the current one, the current message is a useful comparison. If the question is whether either message changes behavior at all, a condition with no message may answer something different.
Some experiments need several comparison conditions. Testing a short instruction, a detailed instruction, and the existing instruction can show which performs better in that setting. But each additional condition should serve a clear question. When reading an experiment, ask what the new approach was compared with. A result described as “better” is incomplete until you know: better than what?
How groups become comparable
Even with a sensible control condition, groups may differ before the experiment begins. People who choose to try a new app feature, for instance, may already be more enthusiastic users. Their later activity cannot automatically be credited to the feature. Random assignment—placing participants into conditions by chance—helps reduce this problem. It does not guarantee identical groups, especially in small experiments, but it makes systematic sorting less likely.
Other design choices matter too. If participants or observers know which condition is expected to perform better, their expectations may affect behavior or how outcomes are recorded. Blinding, when feasible, can limit some of those effects. Researchers also need to consider whether one group’s experience spills over to another—for example, when participants share the experimental message with people assigned to the comparison group. These details affect how confidently a difference can be attributed to the tested change.
What a comparison can—and cannot—tell you
An experiment’s result is usually a difference between conditions, not simply an improvement within one group. If responses rise in both the new-message group and the original-message group, the new message may offer little advantage, even though its group improved. If the groups differ, the size of that difference matters alongside how consistently the outcome was measured and how much uncertainty remains.
A strong comparison supports a narrower conclusion than “this always works.” Results may depend on the people, setting, timing, and particular alternatives tested. When evaluating a claim, look for the outcome measured, the condition used for comparison, how people entered each group, and whether anything else changed. Those questions reveal why control groups are valuable: they do not eliminate uncertainty, but they help identify which explanation the evidence actually supports.