Two questions every measure must answer
Research often turns an idea into something that can be recorded. A survey asks about trust, an observer counts a behavior, or a test assigns a score to a skill. Before interpreting the result, it helps to ask two different questions: Would this measure produce reasonably consistent results under comparable conditions? And does it capture the idea the researcher intended to study? The first question concerns reliability; the second concerns validity.
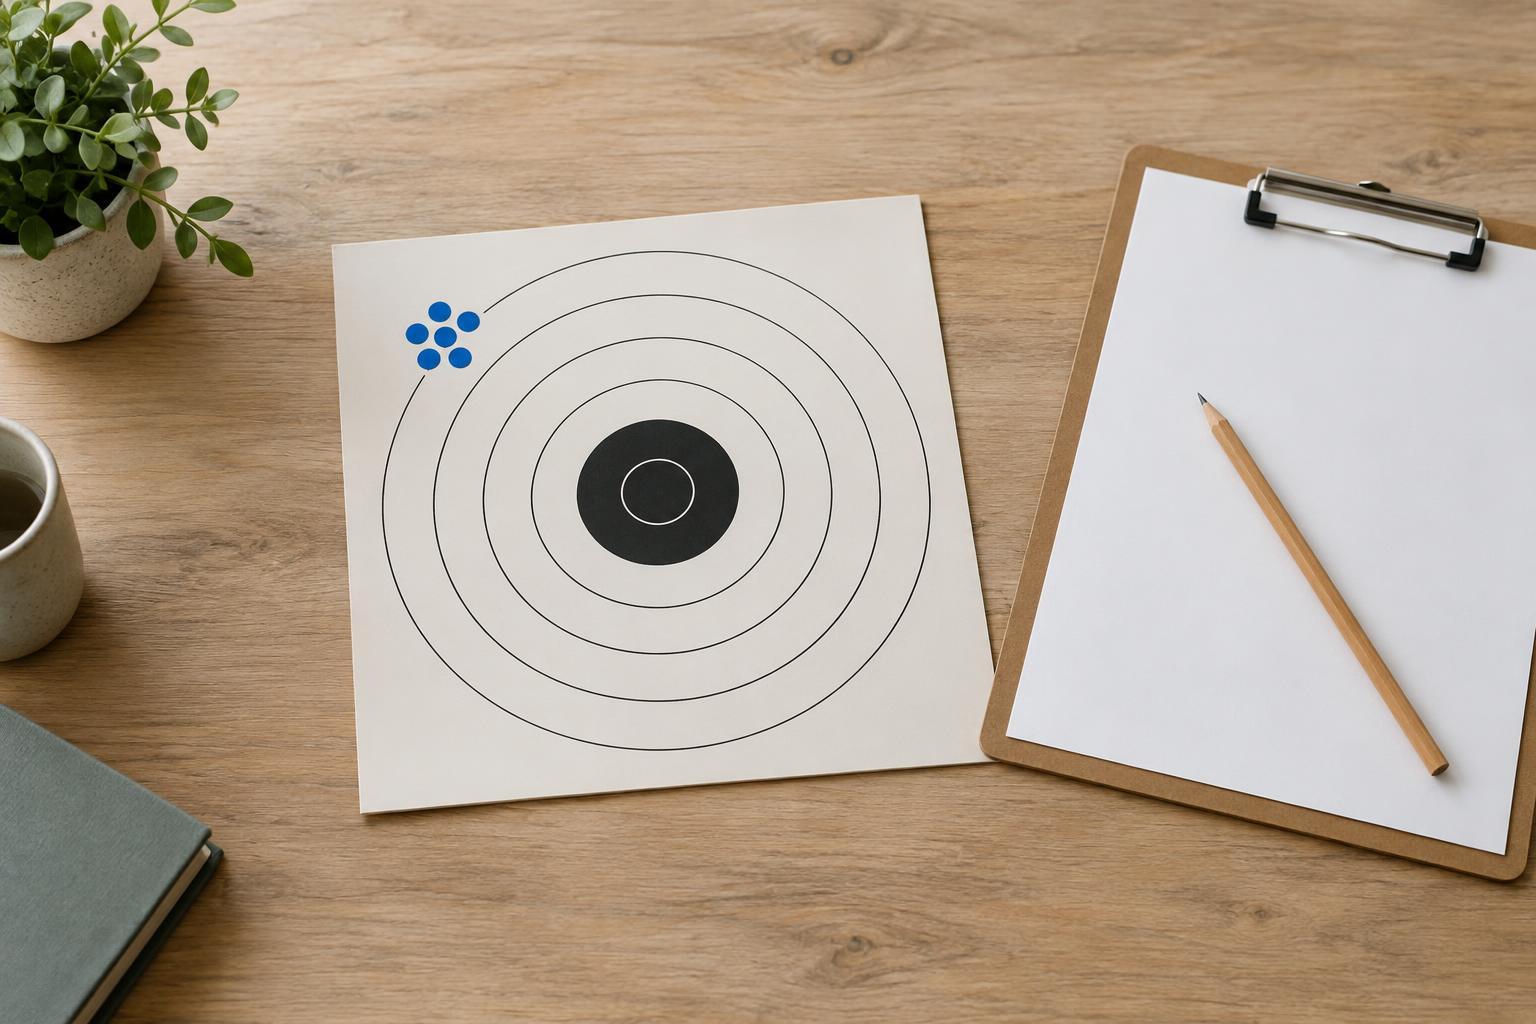
Imagine a bathroom scale that adds the same extra amount every time. Its readings may be consistent, but they do not accurately represent weight. A research measure can have a similar problem. A survey might repeatedly produce the same ranking of customers while asking questions that reflect convenience rather than trust. Consistency alone does not establish that the intended idea has been measured.
What reliability tells you
Reliability concerns the stability or consistency of a measure. If nothing meaningful has changed, a reliable measure should not swing unpredictably. Researchers examine this in different ways depending on the task. They may compare responses collected at two points when the trait is expected to remain stable, check whether different observers record the same behavior, or assess whether questions meant to capture the same idea tend to produce compatible responses.
These checks answer different questions. Agreement between observers matters when people must judge what they see. Stability over time matters when a measure will be used repeatedly. Similarity among survey questions may be useful, but questions should not be nearly identical merely to make their answers match. A measure can also seem unreliable because the situation genuinely changed: a person’s mood today may differ from their mood next week. The goal is to separate meaningful change from noise, not to demand identical results in every circumstance.
What validity asks instead
Validity concerns how well the evidence supports a particular interpretation and use of a measure. If a business calls a short survey a measure of customer trust, do its questions actually address trust? Questions about whether checkout was quick might reveal something about convenience, but they leave out important aspects of trust, such as whether customers expect the business to keep its promises.
One way to examine validity is to look at the measure’s content: does it cover the important parts of the idea without drifting into unrelated topics? Another is to compare its results with other evidence that should, in principle, relate to the same idea. Researchers can also check whether the measure behaves differently from measures of distinct ideas. None of these checks supplies a universal stamp of approval. A measure useful for one purpose, group, or setting may not support the same conclusions elsewhere.
Why one quality cannot replace the other
Reliability and validity are connected, but they are not interchangeable. If a measure produces wildly different scores when the underlying condition is stable, it becomes difficult to draw a sound conclusion from those scores. Improving consistency can therefore help make a measure useful. Yet a highly consistent measure may still miss its target entirely.
Consider a team trying to measure how clearly its instructions explain a process. It could count the number of words on each page and do so with excellent consistency. Word count may describe length, but it cannot, by itself, establish clarity. Readers might understand a longer explanation better than a shorter one. To study clarity, the team would need evidence closer to the intended idea, such as whether readers can explain the steps or complete the task. Even then, it should consider whether the task represents the situations in which the instructions will be used.
A practical checklist before trusting a result
Start by stating the idea in ordinary language. What, exactly, are you trying to learn? Next, inspect what is recorded: the wording of survey questions, the rules observers follow, or the task a test requires. Ask what those records can reasonably reveal and what they leave out. If a score is described with a broad label, such as engagement or confidence, look for a clear explanation of how that label connects to the recorded answers or behaviors.
Then ask how consistency was checked. Would another observer reach a similar judgment? Would a repeat measurement make sense, given how quickly the subject might change? Finally, consider who was measured and under what conditions. A question that works well for one audience may be confusing to another, and a quiet test setting may not resemble everyday use. A pilot with a small group can expose unclear wording or inconsistent procedures before the measure is used more widely.
When reading research, you do not need to decide that a measure is simply good or bad. A more useful conclusion is specific: it appears consistent in these conditions, and the available evidence does—or does not—support this particular interpretation. That distinction keeps a precise-looking number from carrying more meaning than the measure can bear.